
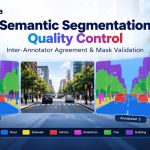
Semantic segmentation plays a critical role in computer vision by assigning a class label to every pixel in an image. From autonomous driving and robotics to medical imaging and retail analytics, segmentation datasets help AI models understand complex visual environments. However, the performance of these models depends heavily on the accuracy and consistency of their training data.
Even small annotation errors, inconsistent labeling decisions, or poorly defined object boundaries can introduce noise into a dataset. Without a structured quality assurance process, these problems may affect model training, evaluation, and real-world reliability.
Quality control for semantic segmentation addresses these challenges through two essential practices: inter-annotator agreement and mask validation. Together, they help organizations maintain consistent labels, identify annotation defects, and build reliable datasets for computer vision applications.
Why Quality Control Matters in Semantic Segmentation
Unlike image classification, which assigns a label to an entire image, semantic segmentation requires pixel-level annotations. Every pixel must belong to an appropriate category according to the project's labeling guidelines.
This level of detail creates several opportunities for errors. Annotators may disagree about object boundaries, classify visually similar categories differently, or overlook small objects. Masks may also contain gaps, unwanted overlaps, or incorrectly labeled regions.
For example, in an autonomous driving dataset, one annotator might classify a partially obscured pedestrian as a person, while another labels the same region as background. Such inconsistencies can affect how a model learns to recognize pedestrians in challenging environments.
A robust quality control framework helps teams identify these issues before datasets enter the training pipeline. It also establishes measurable standards for annotation accuracy, consistency, and completeness.
What Is Inter-Annotator Agreement?
Inter-annotator agreement (IAA) measures how consistently different annotators label the same data under a shared set of guidelines. In semantic segmentation, this assessment focuses on whether annotators assign the same classes to corresponding pixels and interpret object boundaries similarly.
High agreement indicates that labeling instructions are understandable and consistently applied. Low agreement may reveal ambiguous definitions, insufficient training, difficult visual conditions, or disagreements about class boundaries.
However, agreement should not automatically be treated as proof of correctness. Multiple annotators can make the same mistake if the guidelines are unclear. Therefore, agreement metrics should be combined with expert review and independent validation.
Methods for Measuring Inter-Annotator Agreement
Several metrics can help evaluate consistency across segmentation masks.
1. Intersection over Union (IoU)
IoU measures the overlap between two labeled regions. It is calculated by dividing the intersection of the regions by their union.
For two masks representing the same class, a higher IoU indicates greater spatial agreement. IoU is useful for identifying differences in object boundaries, particularly when comparing annotations against an approved reference mask.
2. Dice Similarity Coefficient
The Dice coefficient measures the similarity between two regions by comparing their shared pixels with the total number of pixels in both regions. It is especially useful when evaluating relatively small objects or regions that occupy only a limited portion of an image.
3. Cohen's Kappa
Cohen's kappa measures agreement between two annotators while accounting for the agreement that could occur by chance. It can be useful for categorical labeling comparisons, although its application to segmentation requires careful consideration of pixel-level class distributions and spatial dependencies.
4. Class-Wise Agreement
Overall agreement can conceal weaknesses in minority classes. For example, a dataset dominated by road and sky pixels may achieve high overall agreement even when pedestrian or cyclist annotations are inconsistent.
Evaluating agreement separately for each class helps teams identify underperforming categories and prioritize corrective action.
Mask Validation: Detecting Errors Before Training
Inter-annotator agreement evaluates consistency, while mask validation checks whether segmentation masks satisfy defined technical and annotation requirements. Both are necessary for maintaining dataset quality.
A mask may appear visually acceptable but still contain structural defects that affect downstream processing. Automated validation rules can detect many of these problems before a dataset is approved.
Essential Mask Validation Checks
1. Class Label Verification
Every pixel should contain a valid class identifier according to the project's label schema. Validation scripts should flag undefined class IDs, invalid values, and inconsistent mappings between annotation tools and training pipelines.
2. Boundary Accuracy
Object boundaries should follow the project's annotation policy. Validation should pay particular attention to thin structures, partially visible objects, overlapping visual elements, and areas with similar colors or textures.
For difficult boundaries, reviewers should compare masks against the source images rather than relying exclusively on automated scores.
3. Missing and Incorrect Regions
Quality checks should identify unlabeled pixels, unexpected background regions, and missing objects. Whether unlabeled pixels are acceptable depends on the dataset specification, so validation rules must reflect the agreed annotation policy.
4. Mask Dimensions and Alignment
Each mask must match the dimensions and spatial alignment of its corresponding image. Resizing, cropping, or exporting data incorrectly can shift boundaries and compromise otherwise accurate annotations.
5. Class Distribution Analysis
Unexpected class frequencies may indicate missed objects, inconsistent labeling, or sampling problems. Reviewing class distributions across images and dataset splits helps teams detect anomalies that require further investigation.
6. Visual Inspection
Automated checks cannot identify every semantic mistake. Human reviewers should inspect original images alongside color-coded masks to assess whether labels accurately represent the depicted scene.
Building an Effective Quality Control Workflow
A repeatable quality control workflow makes annotation quality measurable and easier to improve.
Step 1: Establish clear annotation guidelines. Define class descriptions, inclusion and exclusion criteria, boundary conventions, occlusion rules, and treatment of ambiguous pixels. Include visual examples of common edge cases.
Step 2: Conduct annotator training. Before full-scale production, ask annotators to label a shared sample. Review disagreements and clarify confusing instructions before expanding the workload.
Step 3: Introduce independent annotation audits. Assign selected images to multiple annotators without allowing them to see each other's masks. Compare the results using appropriate agreement metrics and expert review.
Step 4: Automate technical validation. Run scripts to verify label IDs, mask dimensions, class distributions, and other dataset-specific requirements. Route failed checks for correction.
Step 5: Apply risk-based sampling. Review a higher proportion of difficult samples, including low-light scenes, rare classes, occlusions, and visually ambiguous boundaries. Random sampling should complement, rather than replace, targeted audits.
Step 6: Maintain a correction and feedback loop. Record recurring errors, identify their root causes, update guidelines, and retrain annotators where necessary. Repeated problems should trigger process improvements rather than isolated corrections alone.
How Annotation Partners Improve Dataset Quality
Managing segmentation quality internally can become challenging when datasets grow across multiple classes, locations, and annotation teams. Specialized providers can introduce standardized workflows, trained annotators, automated checks, and dedicated quality assurance processes.
When evaluating image annotation outsourcing services, businesses should assess how providers measure inter-annotator agreement, validate masks, handle disputed labels, and document corrections. Transparent quality metrics and clearly defined acceptance criteria are more useful than relying on general claims of accuracy.
An experienced image annotation company should also demonstrate the ability to adapt quality control procedures to different use cases, including autonomous driving, robotics, healthcare, and retail computer vision.
At Annotera, structured annotation workflows and quality-focused review processes can help organizations prepare consistent datasets for demanding AI applications. By aligning labeling guidelines, human expertise, and technical validation, teams can reduce avoidable annotation errors and improve confidence in their training data.
Conclusion
Reliable semantic segmentation requires more than detailed pixel-level labeling. It demands systematic quality control that measures annotator consistency, validates mask integrity, and identifies errors before they affect model development.
Inter-annotator agreement helps reveal inconsistent interpretations, while mask validation detects technical defects and missing or incorrect labels. Combined with expert review, risk-based sampling, and continuous feedback, these practices establish a repeatable foundation for dataset quality.
For organizations developing computer vision systems, investing in segmentation quality assurance can support more dependable training data and more informed model evaluation. Partnering with a quality-focused annotation provider such as Annotera can further help teams scale their annotation operations while maintaining consistent standards.