
Artificial Intelligence is evolving beyond systems that understand only text or perform a single task. Modern AI systems are capable of analyzing and comprehending various forms of information, such as text, images, audio, and video. This technology is known as Multimodal Artificial Intelligence. It allows machines to understand information from multiple sources and generate more meaningful responses. If you want to build a strong foundation in emerging AI technologies, consider enrolling in an Artificial Intelligence Course in Tirupur at FITA Academy to develop your knowledge and practical sBlockedword/sentences.
What is Multimodal AI?
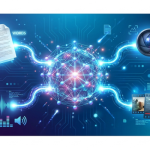
Multimodal AI refers to a category of artificial intelligence capable of processing and comprehending two or more forms of data. Conventional AI models typically concentrate on just one type of data, like text or images. In contrast, multimodal models combine different data formats to understand information more effectively.
For example, a multimodal AI system can analyze an image, understand a question about it, and provide a written explanation. Some advanced systems can also process spoken language, recognize objects in videos, and generate audio responses. This ability helps AI interact with information in ways that are closer to human communication.
How Do Multimodal AI Models Work?
Multimodal AI models work by collecting information from different input sources and converting it into a format that the system can understand. Each data type may require a specialized component for processing.
For example, computer vision components analyze images, while language processing components understand written text. Audio processing components identify speech and sounds. These components work together to combine information and generate an appropriate response.
The model then identifies relationships between different data types. This helps it understand the overall meaning instead of analyzing each input separately.
Key Components of Multimodal AI
Multimodal AI systems rely on several important components to process different types of information.
- Text Processing: Helps AI understand written language, questions, instructions, and descriptions.
- Computer Vision: Allows AI models to identify objects, recognize images, and understand visual information.
- Audio Processing: Helps systems recognize speech, understand sounds, and generate spoken responses.
- Video Understanding: Enables AI to analyze video content, identify activities, and understand events over time.
- Multimodal Fusion: Combines information from different data sources to create a more complete understanding.
These components work together to make multimodal systems more flexible and useful across different applications.
Major Capabilities of Multimodal AI Models
Multimodal AI offers several capabilities that improve how people interact with technology.
- Image Understanding
Multimodal models can examine images, identify objects, recognize visual patterns, and answer questions about image content. This capability is useful in education, healthcare research, and image analysis.
- Audio and Speech Understanding
These models can recognize spoken language, convert speech into text, understand conversations, and generate voice responses. They make communication with AI systems more natural.
- Video Analysis
Multimodal AI can analyze video content to identify objects, activities, and important events. It can also summarize video information and answer questions about specific scenes.
- Text and Image Generation
Some multimodal models can generate images from written descriptions or explain visual content using natural language. This makes them useful for creative work, marketing, and content development.
Real World Applications of Multimodal AI
Multimodal AI is becoming useful across several industries. In healthcare, it can support the analysis of medical images alongside clinical information. In education, it can help students understand concepts through text, diagrams, and voice-based explanations.
In customer service, multimodal systems can understand spoken questions and visual information to provide relevant assistance. In the automotive industry, these technologies can help systems interpret camera feeds, sounds, and other environmental information.
Businesses can also use multimodal AI for document analysis, product recognition, media management, and automated content creation.
Challenges of Multimodal AI
Despite its advantages, multimodal AI faces several challenges. Processing multiple data types requires significant computing resources and large amounts of training data. Combining information from different sources can also be difficult when the data is incomplete or inconsistent.
Privacy and security are additional concerns, especially when systems process personal images, voice recordings, or videos. Multimodal models may also misunderstand visual details or generate inaccurate responses. Therefore, proper testing, data protection, and human supervision are important for building reliable systems.
Multimodal AI is an important development in artificial intelligence because it allows machines to understand and work with different types of information together. Its capabilities in text processing, image recognition, audio understanding, and video analysis are creating new opportunities across industries. As this technology progresses, grasping its basic principles will become more essential for future AI professionals. If you want to expand your knowledge of modern AI technologies and explore practical applications, take the next step by joining Gen AI Courses in Tirupur to strengthen your understanding of generative AI and its growing capabilities.